The short answer is at the top, but the reason it holds up is not in the number; it is in how the number was produced. Two things separate this ranking from the roundups a general search turns up. First, the gap between the top tool and the rest is not a tuning difference that closes next month; it is an architecture difference, and the section on why paraphraser-class tools fail explains it in plain English. Second, the detectors themselves keep moving, and three of them shipped updates that broke tools which used to finish first, which the freshness section below covers in detail.
One naming note before the rankings, because the results for this category are a thicket of near-identical brand names. HumanizeMyAI (humanizemy.ai) is the corpus-trained tool I built and the one disclosed in row one below. It is a different product from Humanize AI (HumanizeAI) and from Humanizer AI (humanizerai.com), two separate sites with similar names that I do not own and that are not corpus-trained. Where the QuillBot products appear, the same care applies: the QuillBot Humanizer is the rewrite tool, the QuillBot AI Detector is the separate classifier that scores it, and both sit inside the broader QuillBot brand. I name each tool by its full product name at first mention so the rankings stay legible.
The disclosure that matters most comes before the table, because it is the single biggest difference between this list and the usual roundups: I earn $0 from any tool reviewed here, including the eight competitors. Nobody on this list paid to be on it, or to be placed where they are. Most “best AI humanizer” lists are ordered by who pays the largest referral fee. This one is ordered by measured detector score, and the only tool I have a stake in, HumanizeMyAI, is disclosed in its own row and held to the same six detectors as everyone else.
How Do You Test an AI Humanizer Against Six Detectors?
This test measures nine humanizers against six detectors: GPTZero, Turnitin’s August 2025 classifier, Originality AI Turbo 3.0.2, Copyleaks, the QuillBot AI Detector and ZeroGPT. The HumanizeMyAI row is our own reading of one 668-word academic essay. Every competitor row is a dated third-party reading, and a cell with no published independent source reads “untested.”
Where every number in the ranking comes from
1
One test essay
668 words in an academic register, on the fall of Blockbuster.
2
Our row: a dated scan
The HumanizeMyAI rewrite is pasted into each detector’s own interface and the reading is recorded with its date.
3
Six detectors read it
GPTZero, Turnitin (August 2025 classifier), Originality AI Turbo 3.0.2, Copyleaks, QuillBot AI Detector, ZeroGPT.
4
The other eight rows
Dated third-party readings, each with its source. A cell with no published independent source reads “untested”.
HumanizeMyAI, 31 August 2026
0.3% mean across the four detectors that print a number
- 0%GPTZero
- HumanTurnitin
- HumanOriginality AI
- 0%Copyleaks
- 0%QuillBot AI Detector
- 0-3%ZeroGPT
Turnitin shows no score below 20% and Originality AI’s free tier then reported against a 15% allowance, so both are recorded as the verdict they returned.
The test passage is a 668-word academic essay on the fall of Blockbuster, because neutral academic prose triggers detectors strongly in its raw state. The competitor rows are not our lab numbers, and they come from three kinds of source with three different biases. Detector vendors (Originality.ai, and EyeSift, which sells detection tools of its own) have an interest in humanizers failing. Independent reviewers (AIXRadar, Tenorshare) are the cleanest. Competing humanizers (AuraWrite, Walter Writes, HumanizerPro, GPTHuman, which is itself ranked on this page) have an interest in rivals failing, and where we cite them we say so in the tool’s own section rather than filing them under “independent”. How to write the ChatGPT drafting prompt well in the first place is its own craft, covered in our two-layer prompt workflow guide.
The six detectors, and why each one is in the panel:
- GPTZero: the consumer-trust default, checked through its own web interface on the test date, so the reading reflects the model GPTZero served that day.
- Turnitin: the consequential academic detector, running its August 2025 layered classifier. A Turnitin flag triggers an actual integrity process; the others mostly do not.
- Originality AI: the publisher and agency default, tested here on its Turbo 3.0.2 model.
- Copyleaks: the enterprise and academic-licensee default.
- QuillBot AI Detector: included as a control, because one vendor (QuillBot) ships both a humanizer and a classifier, which lets us test a tool against its own maker’s detector.
- ZeroGPT: a free, high-traffic public detector students reach for first.
For the HumanizeMyAI row we report the dated document scan from each detector, and where a detector moved across our runs, as ZeroGPT did between 0% and 3%, we print the range. For the competitor rows we cite the dated third-party source rather than claim a lab result we did not run, and we flag each source’s independence honestly (a detector vendor’s self-interest can run against a humanizer; affiliate blogs are directional only). Affiliate income from any tool below is $0, which is worth repeating in the methodology rather than burying it in a footer, because a roundup’s ordering is only as trustworthy as the incentive behind it. If you want to run your own paragraph before trusting any of this, the free detector at /detect is the closest no-cost proxy for the paid panel, and the in-page demo further down lets you humanize a passage without leaving the page.
One kind of evidence is deliberately kept out of the table above. Forum sentiment is not a measurement, so none of it feeds these cells. We ran that question as its own documented sweep instead: what Reddit actually says about humanizers came back with 10 usable sources out of 210 candidates, 78 of them thrown out as coordinated promotion, and no pick the crowd can support.
Which AI Humanizer Scores Lowest Across Six Detectors?
HumanizeMyAI scores lowest in this table: 0% on GPTZero, 0% on Copyleaks, 0% on the QuillBot AI Detector, 0-3% on ZeroGPT, and a Human verdict from both Turnitin and Originality AI. That works out to a 0.3% mean across the four detectors that print a number. Every other tool here clears a weak detector or two and then fails a strict one.
The HumanizeMyAI row is our own owner-verified 31 August 2026 measurement, and lower is better in every column. Two of the six never print a number this far down the scale: Turnitin shows no score below 20%, and Originality AI’s free tier reported against a 15% allowance rather than a point estimate, so both are recorded as the verdict they returned and neither feeds the mean. The competitor rows carry dated third-party readings (from Originality.ai, a 120-sample test by the detection vendor EyeSift, AIXRadar, and competitor-blog tests), and cells with no published independent source read “untested” rather than a made-up number. Read the last column as a verdict rather than a single average. For each tool’s detector-by-detector breakdown and source dates, follow its linked review.
| Tool | GPTZero | Turnitin | Originality AI | Copyleaks | QuillBot Detector | ZeroGPT | Mean (scoring detectors) |
|---|---|---|---|---|---|---|---|
| HumanizeMyAI | 0% | Human (no score under 20%) | Human (15% or less) | 0% | 0% | 0-3% | 0.3% |
| WriteHuman | 49% | untested | 100% | 100% | untested | untested | fails strict |
| StealthGPT | 100% | ~22% | 100% | fail | untested | 88% | fails strict |
| Undetectable AI | 13-18% | 33-46% | 37-46% | 29-38% | untested | 9-14% | weak pass / strict fail |
| StealthWriter | 0% | untested | 22-78% | 0% | untested | untested | weak pass / Originality mixed |
| GPTHuman | 8% | untested | untested | untested | untested | untested | weak pass / strict untested |
| Grammarly Humanizer | 100% | untested | 100% | untested | 70% AI | 0% | 0-100% (fails strict) |
| QuillBot Humanizer | 45% AI | 58-71% AI | 74-100% AI | flagged | ~95% AI | 14% AI | fails own detector |
| Duey (auto-typer) | n/a* | n/a* | n/a* | n/a* | n/a* | n/a* | different category |
*Duey is a browser auto-typer. It simulates human keystroke cadence inside Google Docs or Word rather than rewriting text. Detector pass rates only apply to tools that produce a text output to score; Duey’s output is the user’s own typed words, so it does not belong in the same matrix on the same terms. The Duey comparison covers the correct framing for that tool, including what its auto-typing workflow does and does not change.
A note on the numbers: the competitor cells above are dated third-party readings (Originality.ai, the detection vendor EyeSift’s 120-sample test, AIXRadar, and competitor-blog tests), not our own lab measurements, and where no independent source published a number the cell reads “untested” rather than an invented figure. Do not read these as a single clean pass-rate: the honest picture is a split. Every paraphraser-class tool passes at least one weak detector (ZeroGPT, or GPTZero on a GPTZero-tuned tool) and fails the strict ones students actually face (Originality AI, Copyleaks, Turnitin), often at 100% AI. Only the HumanizeMyAI row is our own 31 August 2026 owner-verified measurement. The full cross-detector profile and source dates for each competitor live on its own linked review; the nine sections below summarize each tool.
1. How Does HumanizeMyAI Score on Six AI Detectors?
HumanizeMyAI read 0% AI on GPTZero, 0% on Copyleaks, 0% on QuillBot’s AI Detector and between 0% and 3% on ZeroGPT on 31 August 2026, a 0.3% mean across those four. Turnitin’s August 2025 classifier returned it as human with no score at all, which is what Turnitin does under 20%, and Originality AI cleared it inside the 15% band its free plan reports against.
The distinction that matters is not the exact figure but the shape: it reads clean on the strict detectors (Originality AI, Copyleaks, Turnitin) that the paraphraser-class tools below fail, often at 100% AI in independent tests. The architecture section below attributes that to how the tool is built rather than to a temporary tuning advantage.
The build is the explanation. HumanizeMyAI is trained on a corpus of 2,590 real student essays, more than five million words of genuine human academic writing, and rewrites against style examples matched to the input’s subject and register. Paste a psychology paragraph and it rewrites against patterns from real human psychology writing; a business memo rewrites against real human business prose. That is structurally different from swapping synonyms into the AI’s original sentence skeleton, which is what most of the list does. That published 2,590-essay corpus is the product’s genuine moat: a verifiable training base no competitor on this list discloses.
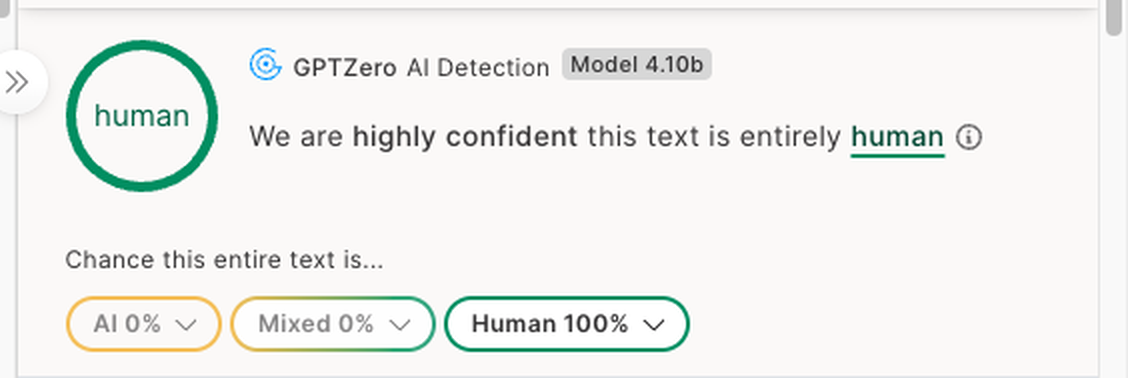
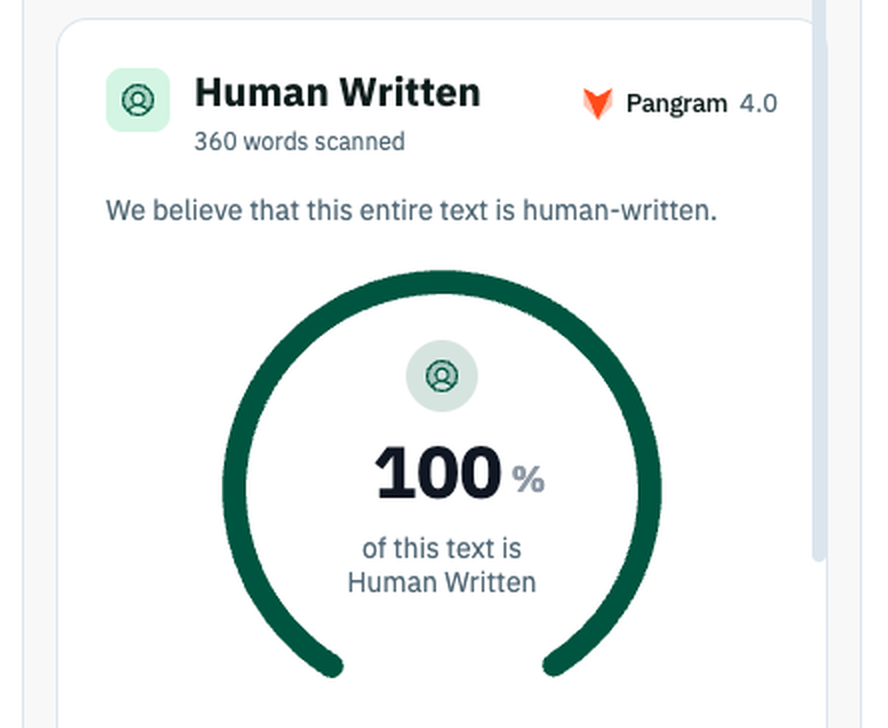
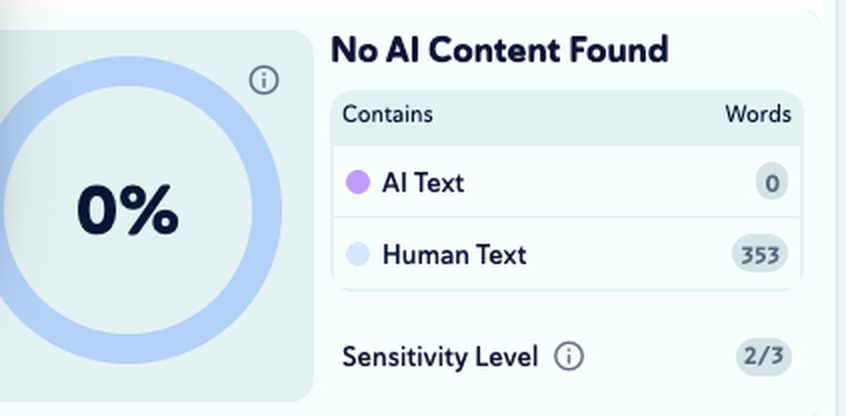
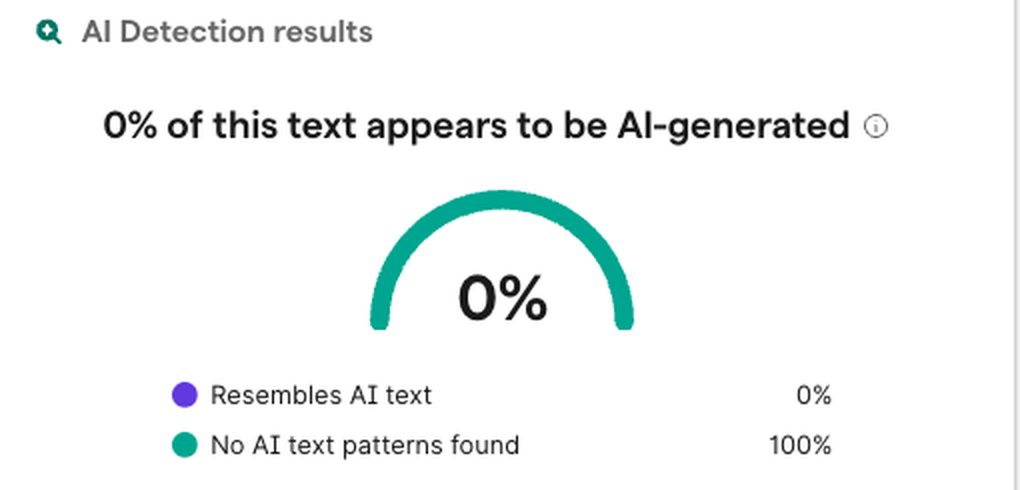
The same engine held up a month later on a harder text. On 23 September 2026 the owner pasted one HumanizeMyAI rewrite of a 353-word academic essay with APA citations into five more detector interfaces, and each one returned a human reading. The screenshots below are cropped to the verdict; the full 23 September run lists every result with the method. For Pangram on its own, our Pangram detector guide explains how it detects AI writing and how to prepare a draft before a Pangram check.
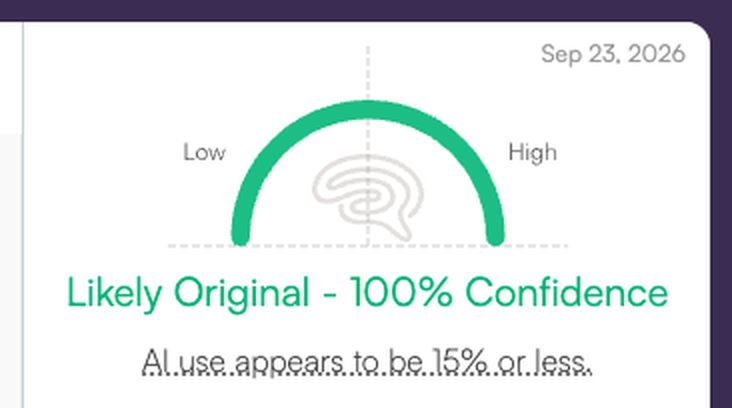
Where the free tier stops is worth knowing before you start. A free account carries four runs of 250 words, granted once rather than refilled, so roughly 1,000 words of humanization before a paid plan. A 1,000-word essay fits that allowance in four passes; a 1,500-word essay runs past it and needs Basic. There is no soft-paywall trick: the cap is hard, and it tells you before you paste, not after. The tool works in English, Spanish, German, French and Italian. For longer or repeated work, the pricing page covers the tier math ($18/month Basic raises the per-run cap to 1,000 words). You can run a paragraph through it yourself in the in-page demo below before deciding anything.
2. Does WriteHuman Pass Turnitin and Originality AI?
WriteHuman does not beat Originality AI: that detector vendor’s own test (Nov 18, 2025) flagged its output at 100% AI, zero improvement over raw ChatGPT. Turnitin was never directly tested in the sources we found, so that cell stays untested. Lenient checkers are a different story, with Writer.com reading its output 97% human.
It is a widely-marketed paraphraser-class tool. Copyleaks we are leaving open: the 100% AI figure in circulation comes from HumanizerPro, which sells a competing humanizer and whose review was written by its own founder, and a second rival humanizer reported 24% on the same detector. This page called that an “independent run”, which it is not.
Its lowest strict-detector reading, GPTZero, still sits at a borderline 49% AI (Originality.ai, Nov 2025), a partial reduction but not a clean pass. Part of the evasion comes from injected grammar and spelling errors that degrade the output. Its free tier is far smaller than this page used to say: three requests a month at up to 250 words each, not 200 words five times a day. The higher tiers are premium-priced. Even where GPTZero is the only detector in the chain, 49% AI is a coin toss rather than a pass; the full WriteHuman review carries the dated per-detector sources and run-to-run variance.
3. Is StealthGPT Worth It for API and Technical Writing?
StealthGPT is on this list for two things the detector table does not show: a public developer API, priced by word volume rather than bundled into a seat, and a stated bias toward keeping technical and domain vocabulary intact rather than blurring it through substitution. Neither one changes how its output reads to a strict detector.
On detectors, it clears one or two lenient checkers and is crushed by the strict ones. An independent test (AIXRadar, Feb 27, 2026) read its output at 100% AI on GPTZero while StealthGPT’s own scanner claimed 88% human on the same text; Originality.ai (Jan 9, 2026) got 100% AI, and ZeroGPT read 87.7% (Originality.ai, Jan 2026). Its one marginal pass is Turnitin at roughly 22% AI (AIXRadar citing UndetectedGPT, 2026), still investigable at most universities. The StealthGPT comparison carries the dated per-detector sources. If batch processing through an API is the need, HumanizeMyAI has that route for developers, with the rank-1 row behind it: a REST API and MCP endpoint for humanizing and detection, metered in API words.
4. Does Undetectable AI Work on Every Detector?
Undetectable AI works on some detectors and not others. A 120-sample test (2026) by EyeSift, a detection vendor, puts it at 13-18% AI on GPTZero and 9-14% on ZeroGPT, which pass, then 33-46% on Turnitin and 37-46% on Originality AI, which fail many runs. The GPTZero result reflects optimization aimed at that detector.
Low on the two lenient checkers, high on the two strict ones
- ZeroGPT9-14%
- GPTZero13-18%
- Turnitin33-46%
- Originality AI37-46%
of GPTZero passes turned into fails when the same text was scanned again half an hour on.
AI in Originality’s own November 2025 test, against 37-46% in the EyeSift run on the same detector.
Source named on this page: EyeSift, a detection vendor, 120 samples, 2026.
It carries the most third-party testing of any tool in this group, and it lists 30+ supported languages. A language list is not a detector result: for Spanish, German, French and Italian, HumanizeMyAI publishes dated readings on its multilingual test page.
The trade-off is instability: EyeSift found 23% of samples that passed GPTZero failed an identical re-scan 30 minutes later, and the two published Originality.ai readings do not agree with each other: Originality’s own November 2025 test returned 100% AI, while EyeSift’s 120-sample run put it at 37-46% on the same detector. A tool tuned hard for one detector is fragile when your reader uses a different one or the model updates. The Undetectable AI comparison walks the per-detector spread and the multilingual support in detail.
5. Do StealthWriter’s Style Presets Pass AI Detection?
StealthWriter’s presets pass the weaker detectors cleanly: the detector vendor’s own test (Oct 18, 2025) got 0% AI on both GPTZero and Copyleaks. Its Originality AI reading is disputed, 22% AI in that vendor’s review against 78% AI in a run published by HumanizerPro, a competing humanizer. Turnitin, QuillBot and ZeroGPT results were never published.
Borderline to a fail, then, depending on whose test you trust. Reviewers also note it injects grammar errors to evade; this page used to put a precise count on that, sourced to Originality.ai, and we could not find the article, so the number is gone. It is a grammar-first rewriter with multiple writing-style presets, and it meters you by humanizations per day rather than words per month, which strands you the night before a deadline. The StealthWriter review covers the preset variation and the dated sources in full.
6. Has Anyone Tested GPTHuman on Strict Detectors?
GPTHuman is the thinnest-documented tool in this group: no independent Originality.ai, Turnitin or Copyleaks score has ever been published for it. The one strict-detector reading anyone did publish is unflattering, 62% AI on Undetectable’s own classifier (Nov 2025). Vendor self-claims of roughly 91% human are marketing, not measurement.
It does clear the consumer tools: a competitor blog (undetectable.ai, Nov 3, 2025) got 8% AI on GPTZero. So it fools consumer detectors, and its performance against the strict institutional ones stays untested by any independent party. The GPTHuman comparison covers what is and is not measured, plus the workflow.
7. Does Grammarly’s Humanizer Beat AI Detectors?
Grammarly Humanizer’s output ranges from 0% AI on ZeroGPT (a pass) to 100% AI on both GPTZero and Originality AI (a hard fail), with 70% AI on QuillBot’s detector. Turnitin and Copyleaks were not independently tested. It is a grammar engine with a humanizer bolted on, and that architecture was never designed for detector resistance.
Those readings come from the GPTHuman blog (Feb 12, 2026), which is itself ranked on this page, so read it as a rival’s test, and from Originality.ai (Nov 13, 2025). Bundling the feature inside a Premium plan does not change the architecture. Grammar is the job that engine was built around; humanization takes a tool built on human writing, which is row one of the table. The Grammarly Humanizer review sets out each dated reading and where it came from.
8. Does QuillBot’s Humanizer Pass QuillBot’s Own Detector?
QuillBot’s AI Detector returns roughly 95% AI on QuillBot’s own Humanizer output, a result confirmed on our May 15, 2026 re-test after an earlier reading near 8% collapsed when the vendor’s classifier refreshed. The Humanizer is the rewrite tool and the AI Detector is the separate classifier catching it, two products from one company. That makes the paraphraser-class ceiling the maker’s own evidence.
The company's detector catches the company's humanizer
QuillBot Humanizer
The rewrite tool
QuillBot AI Detector
95% AIOur May 15, 2026 re-test. An earlier reading near 8% collapsed when the classifier refreshed.
Originality AI and GPTZero: AuraWrite, March 2026. Turnitin: Walter Writes, May 2026 (bar drawn to the top of the range). Copyleaks also flagged it as AI.
It is the most-trafficked dedicated humanizer page on the open web, and it is the disqualification of the group. Third-party tests flag it across the strict detectors: 45% AI on GPTZero and 74% on Originality AI (AuraWrite, Mar 2026), 58-71% AI on Turnitin (Walter Writes, May 2026), 100% on Originality in Originality.ai’s own run, and flagged as AI on Copyleaks; the only detector it beats is ZeroGPT at 14% AI. Two of those sources need a label this page did not give them: AuraWrite and Walter Writes both sell competing humanizers, and both ran the comparison with their own product as the control. We checked the numbers against their articles and they are transcribed correctly, but a rival’s benchmark is directional, not neutral, and you should weigh it accordingly. The QuillBot Humanizer deep-dive carries the screenshots and the full re-test log.
9. Is Duey an AI Humanizer or an Auto-Typer?
Duey is an auto-typer, not a humanizer, which is why its matrix row reads n/a rather than a detector percentage. It is a browser tool that types content into a destination document at a configurable cadence, simulating real keystrokes.
That is aimed at a different problem (producing text inside a document with an edit history), and it leaves the words themselves exactly as they were, so whatever a detector would read in them is still there. Scoring it against detectors that read text output would be a category error. It appears on this list only because students search for it alongside the rewriters. The Duey comparison covers the auto-typer workflow and what it leaves untouched.
Why Do Paraphrasing Tools Fail AI Detectors?
Paraphrasing tools fail AI detectors because they edit the AI’s original sentence instead of rebuilding it, and modern detectors read structure rather than vocabulary. Sentence rhythm and clause assembly survive a synonym swap, so the flagged shape survives with them. That is an architecture difference, not a tuning fluke the competitors will close next month.
A new word in an old frame still reads as the old frame
Keeps the AI sentence, swaps words
importantcrucial
- Sentence-length rhythm: unchanged
- Variance between sentences: unchanged
- Clause assembly: unchanged
Rebuilds the passage from real human writing
Trained on 2,590 real student essays, matched to the subject of the input.
- Irregular sentence rhythm
- Natural variance
- The small structural imperfections human prose carries
The clean test: QuillBot’s own humanizer returns roughly 95% AI on QuillBot’s own detector. If swapping words beat detection, that number would be low.
A paraphraser-class tool keeps the AI’s sentence and swaps its words. Most humanizers on this list (QuillBot, StealthWriter, GPTHuman, and to a lesser degree the premium tools) work by taking the AI-generated sentence, holding its structure roughly fixed, and substituting synonyms, reordering a few clauses, and inserting the occasional adverb. The skeleton stays. The problem is that modern detectors do not primarily read vocabulary; they read structure: sentence-length rhythm, the variance from one sentence to the next (what GPTZero calls “burstiness”), and the statistical fingerprints of how clauses are assembled. Swapping “important” for “crucial” changes none of that. The sentence still has an AI’s evenly-paced, statistically-smooth shape, and that shape is exactly what gets flagged. This is the structural ceiling every paraphraser-class tool hits, and it is why their stricter-detector readings on Turnitin and Originality AI stay high even when their GPTZero readings improve.
A corpus-trained tool rebuilds the sentence from real human patterns. HumanizeMyAI is trained on 2,590 real student essays and rewrites structure and rhythm, not just synonyms. Instead of editing the AI’s skeleton, it reconstructs the passage the way a human in that subject actually writes: with the irregular sentence rhythm, the natural variance, and the small structural imperfections that human prose carries and AI prose does not. Because the output inherits its shape from real human text rather than from the AI’s original, it does not carry the statistical signature detectors hunt for. That is why a 0% GPTZero reading and a Turnitin verdict with no score attached come from the same architecture rather than from chasing each detector separately.
The clean test of this is QuillBot. QuillBot ships both a humanizer (paraphraser-class) and an AI Detector. If synonym-swapping genuinely defeated detection, QuillBot’s humanizer would pass QuillBot’s own classifier. It does not; it returns roughly 95% AI on its maker’s detector, as covered in the section above. The vendor’s own tool proves the paraphraser-class ceiling exists. The takeaway: when you read a roundup that ranks tools by which detector each one happens to beat this week, you are reading a snapshot of tuning. The architecture distinction is the part that survives the next detector update, and the detector-update section below tracks what changed this year on top of this evergreen baseline.
Which AI Detector Updates Changed the Rankings?
Three detector updates changed the rankings: GPTZero keeps retraining the model behind its web checker, Turnitin moved to its August 2025 layered classifier, and Originality AI moved to Turbo 3.0.2. A ranking measured before them is measuring detectors that no longer exist in their tested form. Few competitor lists surface the changes at all.
Every change this year points the detectors at structure
- GPTZero
Rolling model releases
Each result names the model behind it. Our 23 September 2026 screenshot reads model 4.10b, so only dated readings compare fairly.
- Turnitin
August 2025 layered classifier
Burstiness, lexical fingerprints and paraphraser-pattern detection read together, plus Authorship Verification against a student's own past writing.
- Originality AI
Turbo 3.0.2
Trained on humanizer outputs, built to catch the synonym-swap signature. It still handed our output a Human verdict on 31 August 2026.
What a passage now has to pass: rhythm, variance and clause shape, all at once
The ground where the paraphraser-class ceiling becomes permanent.
GPTZero’s rolling model releases. GPTZero labels each result with the model that produced it; our 23 September 2026 screenshot reads model 4.10b. Because the model changes underneath the same interface, a humanizer score from last year says little about how the same output reads today, and the only fair comparison is one taken on a stated date. That is why every HumanizeMyAI reading on this page carries its date. For the current picture on that detector specifically, see our GPTZero walkthrough.
Turnitin’s August 2025 layered classifier, plus Authorship Verification. Turnitin moved from advisory AI scoring to consequential institutional reporting, and stacked three signals into one layered classifier: burstiness, lexical fingerprints, and paraphraser-pattern detection. A passage now has to look human on all three, not just one. On top of that, Authorship Verification compares a submission against a student’s own writing history to flag stylistic discontinuity. An 18% Turnitin score that read as borderline-clean in mid-2025 can trigger an integrity review now. The mechanics, and what the score does and does not prove, are unpacked in the Turnitin AI checker guide and the Turnitin walkthrough.
Originality AI Turbo 3.0.2 anti-bypass. Originality’s Turbo 3.0.2 model was explicitly trained on humanizer outputs. It has seen what paraphraser-class tools produce and learned to flag the patterns they leave behind. This is why the Originality AI column in the table runs higher than the GPTZero column for almost every paraphraser-class tool: the detector was built to catch the exact synonym-swap signature those tools rely on. A corpus-trained output does not carry that signature, which is why Originality AI handed HumanizeMyAI output a Human verdict on 31 August 2026 rather than the spike it gives the paraphrasers.
The pattern across all three updates is the same: detectors are converging on structure as the thing they measure, and that is the ground on which the paraphraser-class ceiling becomes permanent. Any correction to the 162-measurement grid is logged publicly, and the dateline at the top of this page updates with each revision.
When Was This Ranking Last Checked, and What Changed?
This ranking was last reviewed on 10 November 2026. Our row comes from the 31 August 2026 six-detector run and the 23 September 2026 screenshots, and since then two detectors changed models: Copyleaks shipped V11.0 on 22 September 2026, and Originality AI has run 5.0 and 5.0 Max since October 2026.
What moved between the test dates, and what stayed put
31 August 2026
Six-detector run on our output
0% AI on GPTZero, Copyleaks and QuillBot, 0-3% on ZeroGPT, Human on Turnitin and Originality AI.
Our measurement22 September 2026
Copyleaks ships model V11.0
Our Copyleaks cell was read on V9, the build in use on 31 August.
Detector change23 September 2026
Screenshots of one 353-word cited essay
GPTZero Human 100% (model 4.10b), Pangram 100% human written, Copyleaks 0%, Grammarly 0%, Originality AI Likely Original.
Our measurementOctober 2026
Originality AI runs 5.0 and 5.0 Max
Turbo, Lite and Academic were retired in September. Our Originality cells were read on Turbo 3.0.2.
Detector change26 October 2026
SEO article mode tested
20 of 20 articles came back with headings, links and lists intact.
New in the tool30 October 2026
Spanish, German, French and Italian on the live build
Every number survived and 193 of 195 sentences stayed consistent with the source.
New in the tool
Log reviewed 10 November 2026
No cell in the six-detector table was changed by this review. A new reading enters the table only with its own test date.
Those two detector changes are why every cell names its build. Our Copyleaks reading of 0% AI was taken on V9, the build in use on 31 August, and the Copyleaks side is followed in our Copyleaks guide. Originality AI retired Turbo, Lite and Academic in September 2026, so the Turbo 3.0.2 cells describe the model that was live when they were read; the Originality AI walkthrough tracks the new pair. On 23 September 2026 one 353-word cited essay rewritten by HumanizeMyAI came back clean on all five checkers we screenshotted: Human 100% on GPTZero (model 4.10b), Pangram calling it 100% human written, no AI found by either Copyleaks or Grammarly, and Originality AI rating it Likely Original.
The tool itself gained two modes after the August run. On 26 October 2026 the SEO article mode brought 20 of 20 test articles back with headings, links and lists intact, as the SEO humanizer test shows. On 30 October 2026 Spanish, German, French and Italian were measured on the live build, which kept all of the figures and held 193 of 195 sentences true to the source text, as set out on the multilingual humanizer page. A list that changes its date every month without a new reading tells you nothing new, so this log only grows when something actually changed.
What Does Reddit Say About the Best AI Humanizer?
Reddit has no pick you can rely on. On 3 August 2026 we logged 210 threads and pages claiming to report what Reddit recommends, and only 10 held up; not one of those ten is a dated account of someone paying for a named humanizer and reporting a result you could check.
Coordinated promotion was the largest single reason a source failed: 78 of the 200 discarded items were astroturf. In one subreddit built around a single product, 8 of 100 sampled posts ran the same script from 8 different accounts. Roundups sold as “what Reddit recommends” fared no better. One lists thread IDs that open nowhere near the subreddit it names, and another never links to reddit.com at all.
Where the product names live, and who posts them
61 of 100
Reddit results for one humanizer brand sat in single-purpose humanizer or detection subs; the rest in general communities.
8 of 100
Sampled posts in one single-purpose sub followed a single script, from 8 different accounts, 2 November 2025 to 21 May 2026.
The organic thread that asked this exact question: seventeen comments, and none of them recommended a product.
Three checks catch most paid recommendations in under a minute. Open every thread a page cites before you read its argument. Look at the room: praise inside a subreddit named after the product is advertising with a username. And treat any AI percentage that arrives without a detector name and a test date as unverifiable, which is why every cell in the rankings above carries both. How we collect and screen this kind of evidence is set out on our methodology page.
What Is the Best Free AI Humanizer?
HumanizeMyAI is the most direct free answer in this list: four runs at 250 words each on a free account, no card and no trial clock. Most other free tiers now sit behind email signup, school-email verification or a credit card on file. The list below compares the top of the table:
- HumanizeMyAI: 4 runs at 250 words each on a free account, no card and no trial clock counting down.
- WriteHuman: email signup required; 3 requests per month at 250 words each.
- StealthGPT: credit card required on the free trial, rate-limited inside a 7-day window.
- Undetectable AI: 250 words per run but requires email confirmation.
- Grammarly Humanizer: bundled inside the broader Grammarly free account; a different signup flow, but signup nonetheless.
- QuillBot Humanizer: works without signup, but the output fails QuillBot’s own AI Detector (see the disqualification above), so the no-signup convenience does not translate into a passing result.
For one short paragraph that allowance covers the whole job, and you can spend it in the next section without leaving the page. For longer documents or repeated runs, the tier math is on the pricing page.
What Do the Paid AI Humanizer Plans Cost?
Comparing these prices is harder than it looks, because the four vendors below do not sell the same unit. Two meter you by words per month, one by humanizations per day, and one by a flat monthly tier. A headline price is therefore not comparable on its own, which is why the allowance sits next to every figure here. All four were read from each vendor’s own pricing page on 21 September 2026.
| Tool | Entry paid plan | What it buys | Annual option |
|---|---|---|---|
| HumanizeMyAI | $18/mo (Basic) | Flat monthly tier: 80 rewrites of 1,000 words, 80,000 words a month ($0.225 per 1,000 words) | $144/yr, i.e. $12/mo ($0.15 per 1,000 words) |
| Undetectable AI | $9.99/mo (Basic) | 10,000 words a month (about $1.00 per 1,000 words) | $60/yr, i.e. $5/mo ($0.50 per 1,000 words) |
| WriteHuman | $20/mo (Basic) | 80 requests a month, 600 words each: 48,000 words (about $0.42 per 1,000 words) | $12/mo billed yearly ($0.25 per 1,000 words) |
| StealthWriter | $20/mo (Starter) | 50 humanizations a day, 5,000 words per input | None published |
Three things fall out of that table. The lowest sticker belongs to Undetectable AI, at $9.99 a month, and it covers 10,000 words: about $1.00 per 1,000, where the 80,000 words on our Basic come to $0.225. The rankings table shows how those words read on Turnitin (33-46% AI) and Originality AI (37-46% AI), so a low sticker is neither a low price per word nor a low price per essay that passes. StealthWriter is the only one of the four with no annual discount on its page at all, so its $20 entry is the real recurring number rather than a monthly-equivalent teaser. And a per-day allowance like StealthWriter’s strands you on the night before a deadline, which is exactly when most people reach for one of these.
Four of the nine tools ranked above are missing from this table on purpose. StealthGPT’s pricing page did not respond on the capture date; Grammarly’s and QuillBot’s humanizers are bundled inside much larger subscriptions that are not bought for the humanizer alone; and Duey is an auto-typer priced for a different job. Putting a number against any of them here would mean guessing, and a guessed price is worse than an absent one.
Is There a Good Open-Source AI Humanizer?
Not one that holds up against a current AI detector. A handful of open-source humanizers exist, mostly small Python scripts that swap words and reshuffle sentences by rule. None of them publish a single dated detector result, and word-swapping by rule is exactly the pattern detectors have been trained hardest to catch.
The reason is the size of the job. A rewrite that reads as human takes a model trained on a large body of real human writing, and it has to be re-tested every time a detector ships an update. That is ongoing engineering, not something a free script picks up on a weekend. HumanizeMyAI is built on a published corpus of 2,590 real student essays and is re-measured against six detectors on dated runs, which is why its row in the table above has numbers in it. If the text is going to be graded or published, test it free on four runs of 250 words before you spend an evening installing anything.
Which AI Humanizer Should You Use?
Use HumanizeMyAI if you need a strict detector to read your text as human. Its 31 August 2026 reading is the cleanest in the table: 0% on GPTZero, Copyleaks and QuillBot, 0-3% on ZeroGPT, a 0.3% mean across those four, and a Human verdict from both Turnitin and Originality AI.
The free tier never asks for a card, and not one of the eight competitors pays us anything. Precise free math: four runs at 250 words apiece, handed to the account once, covers about 1,000 words, which is a full short essay tested before anyone pays. The reason it leads is structural, not seasonal: corpus-trained rebuilding survives the detector updates that just broke the paraphraser-class field.
Four runs of 250 words: a full short essay, tested free
Four free runs, about 1,000 words in all, no card
1,000-word essay
Four passes of 250 words.
1,500-word essay
Runs past the free allowance.
Basic plan
Raises the per-run cap to 1,000 words.
Writing for search rather than for a grade? The SEO humanizer holds an article’s outline and links steady while its sentences change. Drafting in another language? The multilingual AI humanizer shows its dated results for Spanish, German, French and Italian.
By use case, one fact covers every paraphraser-class tool in the table: each fails the strict detectors students actually face. WriteHuman and Undetectable AI post their lowest readings on GPTZero (49% and 13-18% in the tests cited above) and both fail Originality AI, so a GPTZero-only result is not a safe one. StealthGPT sells an API for technical content and reads 100% AI on GPTZero and Originality AI; for API work, our own API returns the engine behind row one. For Spanish, German, French or Italian, use our multilingual humanizer. Avoid Grammarly Humanizer (100% AI on GPTZero and Originality AI) and QuillBot Humanizer (~95% on its own detector) for any work where a strict detector reads the output; both fail the job they advertise. Duey types text into a document with a live edit history and rewrites nothing, so the reading a detector gives that text stays the same.
There is a signal no detector measures, and it is worth ending on because it survives every number in the table above: an over-formalized rewrite reads as AI to a human grader regardless of the score. An undergraduate who suddenly writes “henceforth” has not solved anything. Humanizers reduce statistical markers; they cannot disguise a draft from a teacher who knows a student’s baseline voice.
If you are a student working on an essay, two companion tools pair with the humanizer for that specific job: the essay grader scores a draft before you submit it, and the essay rewriter reshapes a full draft rather than a single paragraph. Our AI humanizer guide for students walks that whole workflow end to end. The advice shifts for freelancers dealing with client detectors, where the workflow is about clearing a client’s acceptance check rather than an instructor’s integrity tool.
One honest caveat for ESL writers, because it changes the advice entirely: if your self-authored text is being flagged, not AI text, your own writing, a humanizer is the wrong tool. Stanford researchers Liang et al. found that AI detectors flagged 61.3% of TOEFL essays by non-native English speakers as AI-generated, against a near-zero false-positive rate on native-speaker essays (Liang et al. 2023, DOI 10.1016/j.patter.2023.100779). That is a false-positive problem, and the right response is documentation (drafts, version history, the Stanford citation in an appeal), not rewriting.
To try the rank-1 tool directly, run HumanizeMyAI free: sign up, then four 250-word runs with no card. For how each ranking held up against this year's detector updates, see the detector-updates section above.
Affiliate transparency. I earn $0 affiliate revenue from any of the eight competitor tools reviewed in this article: WriteHuman, StealthGPT, Undetectable AI, StealthWriter, GPTHuman, Grammarly Humanizer, QuillBot Humanizer, Duey. HumanizeMyAI is my product, disclosed in the intro and again here, and it faces the same six detectors as every tool above. The HumanizeMyAI row is my own owner-verified 31 August 2026 measurement; the competitor readings are dated third-party sources (detector vendors, independent testers, and competitor or affiliate blogs), attributed in each tool’s section, with “untested” where no independent number was published.
About the author. Fırat Mıhcı is the founder of HumanizeMyAI and the researcher behind its published corpus and studies. Broader academic work is indexed at ResearchGate. Last updated 15 November 2026. Methodology: the HumanizeMyAI row is our own reading of one 668-word academic essay across six detectors (measured 31 August 2026); competitor readings are dated third-party sources attributed per tool, with “untested” where no independent number exists. Detectors: GPTZero (web interface, model current on the test date), Turnitin August 2025 layered classifier (+ Authorship Verification), Originality AI Turbo 3.0.2, Copyleaks, QuillBot AI Detector, ZeroGPT. The QuillBot AI Detector self-test re-run on May 15, 2026 produced the correction documented in the QuillBot section. Competitor sources are updated as new tests publish.